STEP09 Report - Victoria Tier-2
Introduction
The performance of the Victoria Tier-2 site during the STEP09 exercise is reviewed for the three Tier-2 functions of data distribution, monte carlo production and user analysis (glite WMS and panda pilot submissions) via HammerCloud.
Data Distribution
During STEP09 the Victoria site requested a 2% share of the derived dataset distribution of ATLAS data (written to the ATLASDATADISK space token area). Such a value is far less than is planned for the steady-state Tier-2 operations model in the CA cloud where a larger fraction would be subscribed to the Victoria site. Due to storage space constraints at two of the 4 CA Tier-2s the bulk of the subscriptions were targeted toward
SFU (72%) and Alberta (25%). Concurrent with the distribution of ATLAS data to DATADISK was also the distribution of merge AOD samples to the MCDISK space token area. The Victoria share of the merge.AOD sample distribution is 10%.
Figure 1 shows the ATLAS data distribution dashboard summary for the Victoria site for the STEP09 period. In general the transfers to DATADISK were completed successfully for the small amount of data transferred. High load on the SE from too large a number of analysis jobs early on in STEP09 dominated the system activity compared to the WAN transfers.
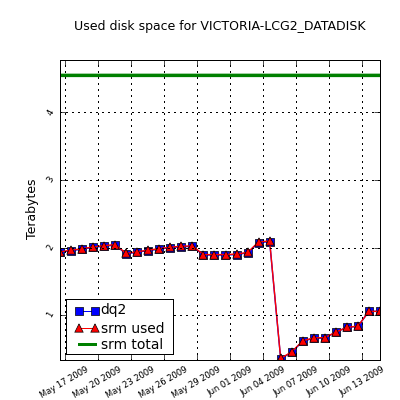
Figure 2 shows the daily growth profile for the Victoria DATADISK and MCDISK areas covering the STEP09 period as taken from the DQ2 Accounting webpages.
Figure 1: Dataset and file transfer rates and errors during STEP09 
 Figure 2: DATADISK and MCDISK occupancy during STEP09

Although only subscribing to 2% of the ATLAS data, several aspects of the Victoria site performance related to the data distribution exercise of STEP09 (and merge AOD replication) should be noted:
SE problems at both Victoria and Toronto with pool failures and under high load (2 June 2009)
- other CA T2s show high rate of successful transfers near 100%
- sites reduced the maximum number of allowed running jobs so as to limit heavy impact upon dcache
- Victoria dCache Setup Notes
- for the Victoria SE the dcache setup consists of 1 dcache admin node and 2 pool servers
- of the two pool servers only one had an available pool, lcg-se2, (ie. with disk space free) to accommodate the majority of incoming data transfers for STEP09 including the MCDISK contents of merge.AODs
- this resulted in a single pool being hit for most analysis requests
- also this pool server (lcg-se2) failed early on in the STEP09 period and just prior to the start of STEP09 due to memory issues
- see attached figures for hot pool node (lcg-se2) network utilization (Figure 10) compared to that of the other pool node (lcg-se1)(Figure 11)
- also shown in Figure 12 is the cpu utlization of the lcg-se2 dcache pool demonstrating the high cpu utlization and io wait present
Victoria and Toronto dCache services stabilized (3 June 2009)
- subsequently removed from Hammercloud blacklist (originally added due to SE and SAM test failures)
VICTORIA_MCDISK becomes full (4 June 2009)
The 12.7 TB of MCDISK space became full. This size was estimated to be sufficient for the 10% share of merge.AOD samples given the centrally defined estimate of merge.AODs totalling approx. 75 TB. At the time of becoming full only 5 of the 259 merge.AOD datasets to go to Victoria were missing. After consultation with ADC Operations there was a central cleaning of mc08*recon.AOD*tid* in VICTORIA-LCG2_MCDISK (to gain 2.7 TB). Datasets data08_cos*tid* in VICTORIA-LCG2_DATADISK (to gain 1.8 TB for the future) was alsocleaned centrally. Time required for cleaning was estimated at a few hours, after which the FTS channel from
TRIUMF was reopened.
Production and Analysis
The Victoria site uses torque + maui as the LRMS. The target shares between production, analysis (WMS) and analysis (panda pilots) for STEP09 were applied in advance of the exercise and checked daily for any problems, either in the targets not being met or if any negative impact on performance was occurring due to the settings (such as total number of jobs).
Below is a snapshot as taken on June 4 showing the target and observed split between each of the job types at the Toronto site. Note the non-use of maui fairshares at the Victoria site which differs from the scheduling policy applied at the other CA T2 sites. Historically the Victoria site admins have found managing job priorities manually to be sufficient for their shared computing facility.
Batch System Shares
Victoria              Jobs             Jobs     Share
                      Running ( %)     Queued   Target (%)*
Production (panda)       65 ( 50%)       35      50
Analysis (WMS)           70 ( 22%)      330      25
Analysis (Panda)         40 ( 28%)       39      25
                        ----------
TOTAL                   175 (100%)

Comment: max number of allowed running jobs decreased from total job
slots to reduce the the frequency of gridftp timeouts.  Site currently does not
employ maui fairshare settings but rather sets soft and hard limits on maxjobs.

* As of 20090604: maxjobs for production/analysis-wms/analysis-pilots = 100/50/50
Production
The Victoria site was not very efficient both in terms of overall average successful job completion (68.8%) although the average cputime to walltime efficiency was good (94.7%) for successful jobs as indicated in the production dashboard snapshot shown in Figure 4.
Figure 4 
The job efficiency (cputime to walltime ratio) as a function of time during the STEP09 exercise is shown in Figure 7 and shows typically job efficiencies of above 95% for most production activities during STEP09, with a dip observed June 9 to the level of around 80%.
Analysis
The final
STEP09 Summary Results
for the analysis jobs submitted to the Victoria site are given below. Overall the Victoria site was more performant for WMS job submissions (73.4% for pilots and 95.9% for WMS jobs). For individual job cputime to walltime efficiency the the pilot submissions were more efficient at 40.8%, but the WMS submissions were only slightly below this at 35.4%.
Figures 8 and 9 demonstrate the measured job throughput (= number of running jobs x the efficiency of those jobs) for each analysis job type. Higher throughput is observed for the Panda pilot analysis jobs particularly in the period up to 6 June. From 6 June onward the throughput of each job type were approximately equal.
Several aspects of the Toronto site performance related to the user analysis component of STEP09 should be noted:
SE problems at both Victoria and Toronto with pool failures and under high load (2 June 2009)
- other CA T2s show high rate of successful transfers near 100%
- sites reduced the maximum number of allowed running jobs so as to limit heavy impact upon dcache
Victoria and Toronto dCache services stabilized (3 June 2009)
- subsequently removed from Hammercloud blacklist (originally added due to SE and SAM test failures)
WMS Analysis Jobs
On average the job efficiency (cputime/walltime) for WMS analysis jobs was approximately 30% as measured from the local torque accounting logs. Job efficiencies as a function of data access method (dcap versus FileStager) cannot be determined from the local site logging information alone but would of course be worthwhile to know for the future Tier-2 deployments in Canada.
The type and frequency of the failures encountered for the WMS analysis job submissions are linked in the table below. A detailed understanding of the reasons associated with the lower success rate compared to that seen with the pilot submissions is still under investigation.
Errors at VICTORIA-LCG2_MCDISK
Panda Analysis Jobs
On average the job efficiency (cputime/walltime) for Panda pilot analysis jobs was approximately 45% from the local torque accounting logs, higher than that for the glite WMS submissions.
The type and frequency of the failures encountered for the Panda pilot analysis job submissions are linked in the table below.
From Figures 5 and 6 it is clearly seen that stable operations were from 6 June onward, after making ajustments to cap the maximum number of running jobs that previously caused excessive load on the site dcache services.
Errors at ANALY_VICTORIA
Conclusions
- data distribution was at the level of 2% for the Victoria site (share of overall ATLAS data distributed). In general various dcache errors observed early-on in STEP09 due to overloaded dcache services from too large a number of WNs actively processing analysis jobs.
- Overall the production proceeded with less overall job success compared to what would have been expected. The Victoria site was not very efficient in terms of overall average successful job completion (68.8%) as indicated in the production dashboard snapshot shown in Figure 4. This requires further investigation.
- Heavy load on dcache at the beginning in particular necessitated capping the maxmum number of allowed analysis jobs of each type to run early on during STEP09. In contrast to what was observed at the other CA Tier2s, the WMS job submissions were more successful than the received pilot analysis jobs. The sucessful pilot jobs still had a higher cputime to walltime efficiency, although in the Victoria case the cputime to walltime efficiency of WMS jobs was only slightly behind on average.
- improvements are foreseen overall for the Victoria Tier-2 capability as it is transitioning to new hardware approximately toward the end of 2009 or early 2010. This will give better network access to each of the dcache pool nodes from the cluster WNs (which there will be more of as well). The new Tier-2 cluster will also present additional challenges in terms of job scheduling as it will continue to be operated in a shared environment with non-ATLAS users (much like is and will be the case with the other CA Tier-2 sites).
Site Tasks for Follow-up
- WMS failed job follow-up and details
- why was CPU efficiency higher?
- Pilot failed jobs - why so high?
- Storage Services
- improvement to services needed
- distribute across more nodes, pool nodes
- scrutinize new T2 dcache design and setup
Figures
Figure 5: Running jobs  Figure 6: Running jobs (cumulative)
 Figure 7: Job Efficiency (cputime/walltime)
 Figure 8: Job Throughput
 Figure 9: Job Throughput (cumulative)
 Figure 10: lcg-sep2 hot pool node network utlization
 Figure 11: lcgsep1 cold pool node network utilization
 Figure 12: lcg-sep2 hot pool node cpu utilization

Additional Material (Sources for dCache Services Performance Metrics)
 AtlasCanada Web>GridActivities>ATLASCanadaTier-2Operations>Step09>Step09SiteReports>VictoriaStep09Report (2009-07-14, BryanCaron)
 EditAttach


 ATLAS
 Alberta
 McGill
 Montreal
 SFU
 Toronto
 TRIUMF
 UVic
 UBC
 Carleton
 IPP
 York
 Create New Topic
 Search


 Copyright © 2008-2026 by the contributing authors. All material on this collaboration platform is the property of the contributing authors.