
Tier1 and Tier-2 Weekly Report 2011-04-05
General News
- ADC and ATLAS Computing News [20110328]
- ADC Weekly http://indico.cern.ch/conferenceDisplay.py?confId=132674
 [20110328]
- ADC Weekly http://indico.cern.ch/conferenceDisplay.py?confId=132674
- CA Cloud Squad Actions [20110329]
- DaTRI requests approved / processed (last week)
- TRIUMF-LCG2_LOCALGROUPDISK: 0 / 0 / 0 GB
- TRIUMF-LCG2-SCRATCHDISK: 3 / 3629 GB / 3629 GB
- Australia-ATLAS_LOCALGROUPDISK: 0 / 0 / 0 GB
- CA-ALBERTA-WESTGRID-T2_LOCALGROUPDISK: 0 / 0 / 0 GB
- CA-SCINET-T2_SCRATCHDISK: 1 / 13 / 13 GB
- CA-SCINET-T2-LOCALGROUPDISK: 82 / 1428 GB / 1428 GB
- CA-VICTORIA-WESTGRID-T2_LOCALGROUPDISK: 1 / 156 GB / 156 GB
- SFU-LCG2_LOCALGROUPDISK: 6 / 485 GB / 485 GB
- Declared Downtimes
- ATLAS Site Exclusion Savannah entries [20110329]
- HammerCloud autoexclusions
- NONE
- HammerCloud autoexclusions
- other cloud squad related savannah and / or ROC ggus tickets [20110322]
- !PD2P (dynamic data placement) in CA cloud [20110405]
- panda monitor for PD2P activity within clouds (default view (last 7 days) units = datasets)
- !PD2P (dynamic data placement) in CA cloud
- DaTRI requests approved / processed (last week)
- Open Issues and Ongoing Discussions
- Sites should be providing the April 2011 storage pledge [see 20110315 report.
- CREAM CE deployment preparations
- TWiki page https://twiki.atlas-canada.ca/bin/view/AtlasCanada/CreamCE [20101019]
- [20110301] Full CREAM-CE deployment awaiting Ganga and WMS testing.
- HammerCloud
- Updated HC tests for UVic to include dedicated 96 core (12 node) test: https://twiki.atlas-canada.ca/bin/view/AtlasCanada/CACloudJan2011 [20110315]
- Test being rerun for Alberta [20110315]
- HammerCloud tests of TRIUMF completed via panda to compare direct i/o via dcap, FileStager and full file copy
- https://twiki.atlas-canada.ca/bin/view/AtlasCanada/TRIUMF_Aug2010
- follow-up required to determine which modifications can be added to Panda schedconfig so as to enable the more efficient FileStager method of data input
- HammerCloud tests of CA clouds sites is planned to be resumed soon to help measure site performance and identify any site setup bottlenecks [2010803]
- Security News [20110329]
- Security ERRATA Critical: java (jdk 1.6.0) - https://rhn.redhat.com/errata/RHSA-2011-0357.html
- Security ERRATA Critical: java (jdk 1.6.0) - https://rhn.redhat.com/errata/RHSA-2011-0357.html
- gLite News [20110329]
- ROC_Canada News [20110329]
- Current shift - Neil Knecht Mar 28-Apr 1
- Next Week - new schedule needed
- Squid Deployment [20110405]
- CA cloud Frontier and Squid deployment information (versions and network information)
- Frontier-Squid Monitoring http://frontier.cern.ch/squidstats/indexatlas.html
- Frontier-Squid Monitoring http://frontier.cern.ch/squidstats/indexatlas.html
- SAM tests: (CA Link), (Aus Link): currently status as of this morning (WARN is ok) [20110329]
- CA-ALBERTA-WESTGRID-T2 OK (OK for local squid; OK backup to SFU)
- CA-SCINET-T2: (ce1) WARN (ce2) OK (both for local squid and backup to SFU)
- CA-VICTORIA-WESTGRID-T2 OK (OK for local squid; OK for backup to CA-ALBERTA-WESTGRID-T2)
- SFU-LCG2 OK (both CEs; both for local squid and backup to CA-VICTORIA-WESTGRID-T2)
- ATLAS_AUSTRALIA - OK (OK for local squid and backup to CA-VICTORIA-WESTGRID-T2)
- TRIUMF-LCG2 OK (ce1) OK (ce2) (local Frontier launchpad and BNL as backup)
- VICTORIA-LCG2 OK (OK for local squid and backup to CA-VICTORIA-WESTGRID-T2)
- CA cloud Frontier and Squid deployment information (versions and network information)
- General Computing News
- SONAR Tests [20110405]
- Performance monitored at http://bourricot.cern.ch/dq2/ftsmon/sonar_view/cached/ . Canadian cloud now tested on Fridays.
- Performance monitored at http://bourricot.cern.ch/dq2/ftsmon/sonar_view/cached/
SAM Results
- site service status via Gridview - Please check your site
- March 30-April 5 2011
- March 2011 Detailed Site Information (valid until 20110430):
- TRIUMF-LCG2
- OPS (this month)

- ATLAS (this month)
- OPS (this month)
- Australia-ATLAS
- OPS (this month)
- ATLAS (this month)
- OPS (this month)
- CA-ALBERTA-WESTGRID-T2
- OPS (this month)
- ATLAS (this month)
- OPS (this month)
- CA-SCINET-T2
- OPS (this month)
- ATLAS (this month)
- OPS (this month)
- CA-VICTORIA-WESTGRID-T2
- OPS (this month)
- ATLAS (this month)
- OPS (this month)
- SFU-LCG2
- OPS (this month)
- ATLAS (this month)
- OPS (this month)
- TRIUMF-LCG2
APEL Accounting
- ACTION ITEM FOR SITES: Sites please regularly check and confirm that your historical APEL data has been published and looks correct when comparing with batch system utilization
- See example steps circulated by D. Qing (20100406)
- See EGEE Accounting Portal (Canada)
- See EGEE Accounting Portal (Australia)
APEL Publishing Status
APEL Accounting Results
APEL Synchronization Test Links
- http://goc-accounting.grid-support.ac.uk/rss/TRIUMF-LCG2_Sync.html
- http://goc-accounting.grid-support.ac.uk/rss/Australia-ATLAS_Sync.html
- http://goc-accounting.grid-support.ac.uk/rss/CA-ALBERTA-WESTGRID-T2_Sync.html
- http://goc-accounting.grid-support.ac.uk/rss/CA-VICTORIA-WESTGRID-T2_Sync.html
- http://goc-accounting.grid-support.ac.uk/rss/CA-SCINET-T2_Sync.html
- http://goc-accounting.grid-support.ac.uk/rss/SFU-LCG2_Sync.html
Site Reports
Alberta
Recent Issues
- summary of this weeks Savannah bugs and GGUS tickets for site:
- production job issues
- See "Production" Activities section below
- analysis job issues
- See "Notes" section below
Outstanding Issues
SFU
Recent Issues
- summary of this weeks Savannah bugs and GGUS tickets for site:
- production job issues
- See "Production" Activities section below
- analysis job issues
- See "Notes" section below
Outstanding Issues
Victoria
Recent Issues
- summary of this weeks Savannah bugs and GGUS tickets for site:
- production job issues
- See "Production" Activities section below
- analysis job issues
- see "Notes" section below
Outstanding Issues
- Occasionally some jobs fail to stage-in .gpg files via scp and have to be terminated. (20100928)
- 201102 - It seems that these jobs are meant to be cancelled, but the lcg-CE, as well as the Cream CE, fail to cancel them.
- 20110308 - The reason that the jobs were never cancelled successfully is a Torque incompatibility with the High Availability feature of Moab. qdel would fail whenever moab02 is the active server, if the full job id is used instead of the short job id. It's because the full job id ends with the address of the moab01 server and torque thinks it should therefore try to contact that server instead of the active one.
Toronto
Recent Issues
- [20110328] Comparing SciNet batch statistics to APEL statistics from the last quarter showed a 10% discrepancy. Identified that job information for lcg-ce1 does not seem to make it into APEL data since 2011-02-17. GGUS ticket issued https://gus.fzk.de/ws/ticket_info.php?ticket=69113
- Updated space tokens on site:
- summary of this weeks Savannah bugs and GGUS tickets for site:
- https://gus.fzk.de/ws/ticket_info.php?ticket=68613 US file transfer errors to the Tier-2's. Failure to send to AGLT2 from SciNet [reassigned 20110322. Believed to correspond to network outage at site. Closed 20110328.]
- https://gus.fzk.de/ws/ticket_info.php?ticket=68613
- production job issues
- See "Production" Activities section below
- analysis job issues
- See "Notes" section below
Outstanding Issues
- [20110307] APEL publishing failing to update information. Auto-yum update of lcg-dgas-tools-1.0.0-2.sl4.i386 to lcg-dgas-tools.i386 1.0.0-4.slc4 on lcg-ce1 on Feb 17 broke the creation of grid-jobmap_YYYYMMDD records.
- Still issues on CE1 - APEL records updated by hand using gatekeeper information [20110315]
- [20110322] lcg-ce1 records are being scraped manually from /var/log/messages and gatekeeper information for the moment. lcg-ce1 needs to be reconfigured (YAIM) but will likely break things.
McGill
Recent Issues
- https://gus.fzk.de/ws/ticket_info.php?ticket=68496 Critical problem in information publish [Last update 20110328 - being worked on]
- https://gus.fzk.de/ws/ticket_info.php?ticket=68613 NAGIOS org.apel.APEL-Pub failed on ce01.clumeq.mcgill.ca@CA-McGill-CLUMEQ-T2 [20110322]
Outstanding Issues
TRIUMF
Recent Issues
- summary of this weeks Savannah bugs and GGUS tickets for site:
- https://gus.fzk.de/ws/ticket_info.php?ticket=69096 ROC_Canada - problem detected: ROD is not functioning properly. [20110328] Related to https://gus.fzk.de/ws/ticket_info.php?ticket=68699
- https://gus.fzk.de/ws/ticket_info.php?ticket=69072 Atlas-16.2.2/i686-slc5-gcc43-opt not validated for reprocessing in TRIUMF. See also http://savannah.cern.ch/bugs/?80087. [20110325]
- https://gus.fzk.de/ws/ticket_info.php?ticket=69022 GGUS-FAQ about Responsible Units
- https://gus.fzk.de/ws/ticket_info.php?ticket=67752 TRIUMF Atlas-16.0.3/i686_slc5_gcc43_opt not validated. Task definition problem - solved [20110222]
- https://gus.fzk.de/ws/ticket_info.php?ticket=66855 Request to WLCG T1s (top-level BDII inquiry) [20110201] (assigned 20110201; ticket updated on 20110216)
- https://gus.fzk.de/ws/ticket_info.php?ticket=67988 some CEs at TRIUMF-LCG2 fail ops glexec tests [20110227] (last update - Di Qing: 20110328 Ready to deploy?)
- https://gus.fzk.de/ws/ticket_info.php?ticket=69096
- production job issues
- See "Production" Activities section below
- analysis job issues
- see "Notes" section below
Outstanding Issues
- HammerCloud tests of TRIUMF completed via panda to compare direct i/o via dcap, FileStager and full file copy [20100827]
- https://twiki.atlas-canada.ca/bin/view/AtlasCanada/TRIUMF_Aug2010
- need to follow-up with panda in regards to appropriate modifications to site description in schedconfig
- PFC creation time and gaps under investigation following production errors [20100729]
- solved by subsequent PFC update but larger issue of PFC update timing needs attention
Australia-ATLAS
Recent Issues
- summary of this weeks Savannah bugs and GGUS tickets for site:
- production job issues
- See "Production" Activities section below
- analysis job issues
- See "Notes" section below
Outstanding Issues
Production
Summary
- NOTE: ARDA ProdSys Dashboard has stopped being used by ADCoS team due to information updating issues with the interface. The historical job usage information is to appear separately within ARDA and is being validated. This will be used in the future for information presented here.
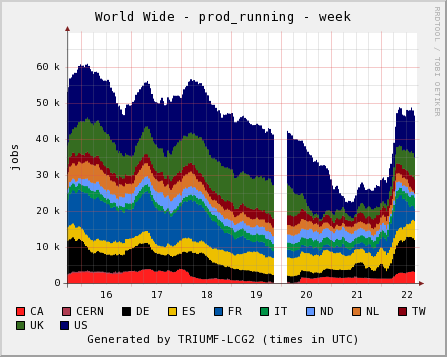
- Within the CA Cloud and Worldwide (Panglia View):


- Alternate Views (Source link for last 7 days):
- http://dashb-atlas-prodsys.cern.ch/dashboard/request.py/summary?cloud=TRIUMF&grouping=site&grouping=cloud&end-date=2011-03-22%2020:59:59&start-date=2011-03-15%2020:00:00
Time interval:   2011-03-15 18:00:00   to   2011-03-22 00:00:00
          (finished/failed)

Worldwide Production by Cloud:
   US (673292/45662)
   DE (269590/22173)
   FR (254053/30243)
   UK (179144/22282)
   ES (110590/10557)
   CERN (109413/10393)
   NL (102049/6521)
   CA (72221/24633)
   IT (66051/11811)
   ND (68313/6584)
   TW (58872/5503)

Production:
   TRIUMF (14391/19607)
   CA-SCINET-T2 (9649/131)
   CA-VICTORIA-WESTGRID-T2 (3286/148)
   SFU-LCG2 (2947/23)
   CA-ALBERTA-WESTGRID-T2 (1949/5)
   Australia-ATLAS (629/31)

Analysis:
   ANALY_TRIUMF (12131/900)
   ANALY_SCINET (11335/1005)
   ANALY_ALBERTA-WG1 (4521/326)
   ANALY_SFU (4456/312)
   ANALY_SFU_bugaboo (2539/1726)
   ANALY_AUSTRALIA (2499/273)
   ANALY_VICTORIA-WG1 (1889/146)
Failed Jobs
- From Panda Monitor (last day)
- My Notes:
- Highlight's of Yuri's notes: (Mar 22-28, 2011)
A)  During the past week (Mar.22-28,2011) Panda production service
   - completed 1,256,051 managed group, MC production, validation
     and reprocessing jobs
   - average ~179,436 jobs per day
   - failed 64,068 jobs
   - average efficiency:
      -- jobs     - 95.1%
      -- walltime - 96.5%
   - active tasks from Panda-monitor: 266
      -- distribution by cloud:
     CA:9 CERN:3 DE:55 ES:15 FR:79 IT:8 ND:10 NL:21 TW:3 UK:30 US:33

B)    - new DB Release 14.8.1,14.9.1 subscription done, Mar.23,24.
   - new pilot version SULU 46c created, Mar.24.
   - HI reprocessing campaign almost completed (some remaining tails).

3) Thu Mar.24
+ CA/TRIUMF-LCG2 repro t.283287 job f./Get er.:Failed to get LFC replicas.
  GGUS 68909 solved:time synchronization problem on Grid Canada CA server
  fixed.Task DONE.
- DE/MaiGRID_LOCALGROUPDISK<-TRIUMF 36 FT f./GRIDFTP_ER:server er.426.GGUS
  68926 assigned:more errors on Mar.27.

4) Fri Mar.25
- CA/TRIUMF t.288995,289029 job f./tlas-16.6.2/i686-slc5-gcc43-opt not
  validated.Savannah 80087:seems related to a new queue(ce3.triumf.ca).
  The queue was set offline.GGUS 69072 in progress.

7) Mon Mar.28
- ES/PIC<-TRIUMF 85 FT f./GRIDFTP_ER.:server err.426.GGUS 69110 in
  progress.
-- LeslieGroer - 2011-04-05  Edit | Attach |
Topic revision: r2 - 2011-03-29 - LeslieGroer
Navigate ATLAS-Canada Wiki:
- * Home* * Activities * Analysis
- Computing
- Datasets
- Getting Started
- Grid Activities
- * Meetings* * People in ATLAS Canada * User Services
- Travel To CERN
Wikis:
 ATLAS
 Alberta
 McGill
 Montreal
 SFU
 Toronto
 TRIUMF
 UVic
ATLAS-Canada Institute Websites:
 UBC
 Carleton
 IPP
 York
 Create New Topic
 Search
 |
|

 Copyright © 2008-2026 by the contributing authors. All material on this collaboration platform is the property of the contributing authors.
Ideas, requests, problems regarding TWiki? Send feedback