TWiki> AtlasCanada Web>GridActivities>ATLASCanadaTier-2Operations>T2WeeklyReport20100824 (2010-08-24, BryanCaron)
 EditAttach
AtlasCanada Web>GridActivities>ATLASCanadaTier-2Operations>T2WeeklyReport20100824 (2010-08-24, BryanCaron) EditAttachTier1 and Tier-2 Weekly Report 2010-08-24
General News
- ADC News [20100824]
- This Week
- Upcoming LHC Technical Stop: Monday August 30 to Thursday September 2
- ADC Weekly [20100823]
- http://indico.cern.ch/conferenceDisplay.py?confId=104383

- Highlights:
- dataset and lfn character length limitations - see talk for details
- heavy ion data processing tests - running since Aug 19 with 100% efficiency and expected to be kept going for the rest of the week
- tasks within Panda dashboard: (link)
- https://twiki.cern.ch/twiki/bin/view/Atlas/ADCHI2010
- tasks within Panda dashboard: (link)
- http://indico.cern.ch/conferenceDisplay.py?confId=104383
- Upcoming Events
- ATLAS future and upgrade computing mini-workshop @ LBL scheduled for September 16, 17 2010
- This Week
- CA Cloud Squad Actions [20100824]
- DaTRI requests for approval
- ATLAS Site Exclusion Sannah entries created
- CA-VICTORIA-WESTGRID-T2: scheduled downtime (DDN storage issues) [20100823] https://savannah.cern.ch/support/?116350
- SFU-LCG2: scheduled downtime (power switch upgrade) [20100823] https://savannah.cern.ch/support/?116349
- CA-ALBERTA-WESTGRID-T2: scheduled downtime (short CE and SE work) [20100823] https://savannah.cern.ch/support/?116388
- CA-VICTORIA-WESTGRID-T2: scheduled downtime (DDN storage issues) [20100823] https://savannah.cern.ch/support/?116350
- queue operations
- CA-VICTORIA-WESTGRID-T2: analysis and production queues set to test [20100818] by cloud squad due to DDN storage issues and scheduled downtime
- SFU-LCG2: analysis and production queues set to test [20100823] by cloud squad due to scheduled downtime (power switch upgrade)
- Australia-ATLAS: queues set to test [20100819] by cloud squad due to scheduled downtime (disk server work)
- returned to online status by ADCoS shifters [20100819]
- submitted savannah ticket to dashboard support inquiring why the CA-VICTORIA-WESTGRID-T2 site is not visible within the SAM ATLAS View [20100823]
- Missing Files at TRIUMF-LCG2_MCDISK (Panda ID 1101024400 and 1101024401) [20100818]
- DQ2-DDM Operations Savannah http://savannah.cern.ch/bugs/?71573
- DDM site services missed copying 2 of 252 files of the subdataset from source (SFU) to destination (TRIUMF); under investigation by DDM Operations
- DQ2-DDM Operations Savannah http://savannah.cern.ch/bugs/?71573
- CA-VICTORIA-WESTGRID-T2 site missing from the ATLAS dashboard SAM Visualization page [20100824]
- submitted bug report to Dashboard Savannah https://savannah.cern.ch/support/index.php?116392
- submitted bug report to Dashboard Savannah https://savannah.cern.ch/support/index.php?116392
- HammerCloud tests of TRIUMF completed via panda to compare direct i/o via dcap, FileStager and full file copy
- Open Issues and Ongoing Discussions:
- Pending action: update values for maxinputsize for SFU-LCG2 (snowpatch and bugaboo) within panda schedconfig [20100817]
- HammerCloud tests of CA clouds sites is planned to be resumed soon to help measure site performance and identify any site setup bottlenecks [2010803]
- discussion with DDM operations regarding centrally performed space cleaning policy and procedures [20100721]
- context is the SFU MCDISK blacklisting as discussed in http://savannah.cern.ch/support/?115809
- new savannah entry about cleaning policy and procedures: http://savannah.cern.ch/bugs/?70746 (closed)
- topic is to be discussed at the next DDM meeting (TBA)
- new savannah entry about cleaning policy and procedures: http://savannah.cern.ch/bugs/?70746
- context is the SFU MCDISK blacklisting as discussed in http://savannah.cern.ch/support/?115809
- submitted feature request to DaTRI to allow for disabling of auto-approval for LOCALGROUPDISK transfer requests [20100720]
- CA-VICTORIA-WESTGRID-T2 site analysis queues marked online by Cloud Squad (20100709)
- production queue kept in test state pending investigation of fortran runtime error "permission denied" within software release area (20100708) [SOLVED]
- resolved by changing WN client NFS mounts to v3 from original NFSv4 (root cause within NFSv4 still unknown) [OPEN]
- production queue kept in test state pending investigation of fortran runtime error "permission denied" within software release area (20100708) [SOLVED]
- ROOTSYS truncated at 127 characters issue [20100608]
- http://savannah.cern.ch/bugs/?68546 (open)
- currently affecting Victoria (Tier3) and CA-SCINET-T2
- varying character lengths below and above 127 characters show variable success and failure
- related issue: user build jobs failing at CA-SCINET-T2 [20100511]
- follow-up with site in regards to missing rpm installation; missing rpms added but problem is still occurring [20100518]
- http://savannah.cern.ch/bugs/?68546
- escalate query to ATLAS dashboard support regarding missing CA-SCINET-T2 site in the ARDA dashboard production activity display [20100216]
- reminder message posted to the Dashboard Savannah entry for this problem https://savannah.cern.ch/bugs/index.php?64507 [20100518] (updated 20100824)
- reminder message posted to the Dashboard Savannah entry for this problem https://savannah.cern.ch/bugs/index.php?64507
- reviewing draft Squad How-To and providing feedback [20100407]
- also contains useful information for sites
- ongoing discussions with ADC experts regarding regional production activity and how to accommodate it cleanly within both the production system and the CA cloud and site operations [20100316]
- running out of jobs at TRIUMF (and other CA cloud sites other than CA-SCINET-T2) [20100402]
- "The problem may be due to the jet/group production task. Since these jobs have high priority, they are being sent to CA cloud, to the exclusion of lower prio jobs. Of course, they can only run at one site. So, other sites are running empty. Unanticipated side effect of running the task only at CA-SCINET-T2! Let me think how to solve it." K. De (ADC)
- request submitted to Panda team for functionality to set site Panda queues offline automatically based upon scheduled outages/availability [20100216]
- Savannah http://savannah.cern.ch/bugs/?62993 (ticket closed 20100301 but discussion ongoing within Panda team regarding which BDII variables to query)
- Savannah http://savannah.cern.ch/bugs/?62993
- Outstanding Actions to Do:
- follow-up information system publishing by dCache sites and use of FileStager within GangaRobot [20100111]
- ie. dcap missing from TRIUMF and CA-ALBERTA-WESTGRID-T2 and so uses lcg-cp.
- follow-up information system publishing by dCache sites and use of FileStager within GangaRobot [20100111]
- ROC_Canada News [20100824]
- current shift schedule (until Sept 24): https://twiki.atlas-canada.ca/bin/view/AtlasCanada/ROCShifts
- new version of GOCDB4 Central Visualisation Portal online: https://next.gocdb.eu/portal/
- Squid Deployment [20100824]
- CA cloud Frontier and Squid deployment information (versions and network information)
- SAM tests: (CA Link), (Aus Link): currently status as of this morning (WARN is ok) [20100720]
- CA-ALBERTA-WESTGRID-T2 OK (both for local squid and backup to SFU squid)
- CA-SCINET-T2: OK (local squid server online and active for both lcg-ce1 and lcg-ce2; backup to SFU squid)
- CA-VICTORIA-WESTGRID-T2 OK (both for local at VICTORIA-LCG2 and backup to SFU squid)
- SFU-LCG2 OK (both CEs; local squid is OK; backup squid at VICTORIA-LCG2 OK)
- VICTORIA-LCG2 OK (OK for local squid and connection to SFU squid)
- ATLAS_AUSTRALIA - OK (local squid OK; backup to VICTORIA-LCG2 OK)
- TRIUMF-LCG2 OK (ce1) OK (ce2) (local Frontier launchpad and BNL as backup)
SAM Results
- draft July 2010 WLCG Tier-2 availaibility and reliability report issued [20100810]
- http://gvdev.cern.ch/GRIDVIEW/downloads/Reports/201007/wlcg/lcg_tier2_rel_jul2010.pdf
- ACTION ITEM: sites with low values should please comment = Australia-ATLAS, CA-SCINET-T2, CA-ALBERTA-WESTGRID-T2
- http://gvdev.cern.ch/GRIDVIEW/downloads/Reports/201007/wlcg/lcg_tier2_rel_jul2010.pdf
APEL Accounting
- ACTION ITEM FOR SITES: Sites please regularly check and confirm that your historical APEL data has been published and looks correct when comparing with batch system utilization
- See example steps circulated by D. Qing (20100406)
- See EGEE Accounting Portal (Canada)
- See EGEE Accounting Portal (Australia)
APEL Publishing Status


APEL Accounting Results


Site Reports
Alberta
Recent Issues
- summary of this weeks Savannah bugs and GGUS tickets for site:
- https://gus.fzk.de/ws/ticket_info.php?ticket=61237 NAGIOS org.sam.SRM-Put-/ops/Role=lcgadmin failed on se01.atlas.ualberta.ca@CA-ALBERTA-WESTGRID-T2 (20100817) [solved 20100817]
- http://savannah.cern.ch/bugs/?68656 DDM Operations: SCRATCHDISK shows DQ2 larger than srm_total on DQ2 accounting (20100610) (in progress)
- https://gus.fzk.de/ws/ticket_info.php?ticket=59747 gstat 'check-se' problem detected at CA-ALBERTA-WESTGRID-T2 (20100705) (on hold)
- https://gus.fzk.de/ws/ticket_info.php?ticket=61237
- production job issues
- See "Production" Activities section below
- analysis job issues
- See "Notes" section below
- CA-ALBERTA-WESTGRID-T2 site status [20100824]
- ongoing work with DDN and multipath setup to add minimum of 6 new LUNs to the site dCache
- dCache SRM space usage discprepancy work-around to be tested next week during LHC technical stop (postponed from previous weeks)
- short scheduled downtimes planned for 20100826 (approx. 6 hours) to add new LUNs to dCache and relocate ATLAS software area to a larger LUN
- ADC Site Exclusion Savannah
- CE downtime (20100825 - 2010826) https://next.gocdb.eu/portal/index.php?Page_Type=View_Object&object_id=20248&grid_id=0
- SE downtime (20100826) https://next.gocdb.eu/portal/index.php?Page_Type=View_Object&object_id=20249&grid_id=0
Outstanding Issues
- DDM: discrepancy between SRM and DQ2 usage (see above savannah) [20100511]
- tests on postgres dump of dCache databases pending
- additional open items being followed-up:
- need to update to dCache golden release cycle from currently running 1.9.3-3 - targetting mid-September for upgrade
- performance of fairshare trees configuration to be studied with WestGrid site admins in regards to priorities, non-NRAC allocations and effect upon priority of ATLAS jobs
- network cabling maintenance planned for lighpath connection [postponed from 20100319]
SFU
Recent Issues
- summary of this weeks Savannah bugs and GGUS tickets for site:
- https://gus.fzk.de/ws/ticket_info.php?ticket=61344 NAGIOS org.sam.SRM-Put-/ops/Role=lcgadmin failed on wormhole.westgrid.ca@SFU-LCG2 (20100820) [solved 20100821]
- https://gus.fzk.de/ws/ticket_info.php?ticket=61345 SFU-LCG2 - jobs failing at stage-out - "Globus system error: /opt/lcg/bin/lcg-cr" (20100820) [verified 20100820]
- https://gus.fzk.de/ws/ticket_info.php?ticket=61344
- production job issues
- See "Production" Activities section below
- analysis job issues
- See "Notes" section below
- scheduled downtimes this week for bugaboo (CE) and WNs
- ADC Site Exclusion Savannah https://savannah.cern.ch/support/?116349
- bugaboo CE and queue draining (20100823) https://next.gocdb.eu/portal/index.php?Page_Type=View_Object&object_id=20200&grid_id=0
- machine room power switch upgrade (20100824) https://next.gocdb.eu/portal/index.php?Page_Type=View_Object&object_id=20136&grid_id=0
- bugaboo CE and queue draining (20100823) https://next.gocdb.eu/portal/index.php?Page_Type=View_Object&object_id=20200&grid_id=0
- ADC Site Exclusion Savannah https://savannah.cern.ch/support/?116349
- scheduled downtime next week (full SFU site)
- major network upgrade between Vancouver downtown and SFU burnaby campus (20100829) https://next.gocdb.eu/portal/index.php?Page_Type=View_Object&object_id=20137&grid_id=0
- major network upgrade between Vancouver downtown and SFU burnaby campus (20100829) https://next.gocdb.eu/portal/index.php?Page_Type=View_Object&object_id=20137&grid_id=0
Outstanding Issues
Victoria
Recent Issues
- summary of this weeks Savannah bugs and GGUS tickets for site:
- https://gus.fzk.de/ws/ticket_info.php?ticket=60975 SRM Authentication failed from CA-VICTORIA-WESTGRID-T2_SCRATCHDISK to PIC_SCRATCHDISK [20100808] (verified 20100814)
- https://gus.fzk.de/ws/ticket_info.php?ticket=60975
- production job issues
- See "Production" Activities section below
- analysis job issues
- see "Notes" section below
- (un)scheduled downtimes starting 20100819 due to DDN array issues
- ADC Site Exclusion Savannah https://savannah.cern.ch/support/?116350
- unscheduled downtime (20100819 to 20100823) https://next.gocdb.eu/portal/index.php?Page_Type=View_Object&object_id=20138&grid_id=0
- scheduled downtime (20100821 to 20100826) https://next.gocdb.eu/portal/index.php?Page_Type=View_Object&object_id=20201&grid_id=0
- unscheduled downtime (20100819 to 20100823) https://next.gocdb.eu/portal/index.php?Page_Type=View_Object&object_id=20138&grid_id=0
- 2 failed LUNs in the same tier in our DDN (DCS 9900)
- 2 LUNs which have 2 failed disks and errors and potential failure in a 3rd disk
- all failures so far have been in the 12 dCache LUNs allocated last week
- updated rebuilding parameters to match that of TRIUMF DDN (128 MB at a time)
- system was running without disk verification since it was disabled by vendor for benchmarking ; now enabling bad block management
- working with IBM and DDN support
- ADC Site Exclusion Savannah https://savannah.cern.ch/support/?116350
- new site squid host (sphinx.westgrid.ca) under final testing before being added to ToA
Outstanding Issues
Toronto
Recent Issues
- summary of this weeks Savannah bugs and GGUS tickets for site:
- https://gus.fzk.de/ws/ticket_info.php?ticket=58997 Many jobs Get error: Failed to get LFC replicas at CA/CA-SCINET-T2 (2010-06-13) (solved 2010-06-13)
- re-opened and marked unsolved (20100709)
- https://gus.fzk.de/ws/ticket_info.php?ticket=58116 LFC error at CA/CA-SCINET-T2 (20100510) (unsolved 20100709)
- http://savannah.cern.ch/bugs/?65337 CA-SCINET-T2 pilot: Job killed by signal 15 [20100405](open)
- https://gus.fzk.de/ws/ticket_info.php?ticket=58997
- production job issues
- See "Production" Activities section below
- analysis job issues
- See "Notes" section below
- LFC access timeout debugging and resolution [20100818]
- problems coincident with LFC dumps which occur every 3 hours
- increased number of threads of LFC daemon from 40 to 60 as well as reverted to previous configuration pre-upgrade of not locking tables during the database dump
- successfully eliminated observed failures at scinet
- TORONTO-LCG2 site
- site offline to ATLAS; currently suspended by CA_ROC in GOCDB
- https://gus.fzk.de/ws/ticket_info.php?ticket=53830 TORONTO-LCG2 update to lcg-CE (20091203) [on hold]
- https://gus.fzk.de/ws/ticket_info.php?ticket=53605 TORONTO-LCG2 lcg_cp timeout (20091124) [on hold]
Outstanding Issues
- pilot issues [20100511]
- significant number of immediately failing pilots for both TRIUMF and LMU factories
- need to logon to WN directly and run the wrapper script by hand
- dCache error investigations
- Occassional "There is no file with pnfsid=.." errors (20100430)
- under discussion with dCache experts at TRIUMF and elsewhere
- dCache PutUseSpaceCallbacks errors (20100504)
- Occassional "There is no file with pnfsid=.." errors (20100430)
- large number of LFC related errors (20100404)
- 'Put error: lfc_setfsizeg failed' and 'lfc_statg failed' and 'errstr = Bad magic number'
- SciNet-TRIUMF lightpath network use and optimization [20100413]
- BGP established on Force 10 router for link to TRIUMF [20100407]
- Information Request: is a failover test to the ORAN planned? A: Not yet.
- BGP established on Force 10 router for link to TRIUMF [20100407]
- observed high rate of job failures for pilots submitted via CERN factory compared to those from LMU and TRIUMF [20100322]
- different network path observed from CERN to Scinet compared to from LMU. Pilots from CERN halted pending investigation
- discussion with pilot factory experts ongoing regarding interplay between condorg and globus gma, and local adjustments to correct the 33% of all pilots which fail on WNs * "submit-helper script running on host gpc-f108n039 gave error: cache_export_dir (/localstorage/lcg/home/prdatl83/.lcgjm/globus-cache-export.W29972) on gatekeeper did not contain a cache_export_dir.tar archive"
TRIUMF
Recent Issues
- summary of this weeks Savannah bugs and GGUS tickets for site:
- https://gus.fzk.de/ws/ticket_info.php?ticket=59748 gstat 'check-se' problem detected at TRIUMF-LCG2 (20100705) (on hold 20100706)
- https://gus.fzk.de/ws/ticket_info.php?ticket=59748
- production job issues
- See "Production" Activities section below
- analysis job issues
- see "Notes" section below
- HammerCloud tests of TRIUMF completed via panda to compare direct i/o via dcap, FileStager and full file copy
- LFC and database dump modifications to resolve communications errors observed previously by scinet [20100818]
- Missing Files at TRIUMF-LCG2_MCDISK (Panda ID 1101024400 and 1101024401) [20100818]
-
- DQ2-DDM Operations Savannah http://savannah.cern.ch/bugs/?71573
- DDM site services missed copying 2 of 252 files of the subdataset from source (SFU) to destination (TRIUMF); under investigation by DDM Operations
- DQ2-DDM Operations Savannah http://savannah.cern.ch/bugs/?71573
-
- upcoming Tier-1 maintenance work during LHC Technical Stop next week (Aug 30 - Sept 2)
Outstanding Issues
- PFC creation time and gaps under investigation following production errors [20100729]
- solved by subsequent PFC update but larger issue of PFC update timing needs attention
Australia-ATLAS
Recent Issues
- summary of this weeks Savannah bugs and GGUS tickets for site:
- https://gus.fzk.de/ws/ticket_info.php?ticket=61132 jobs failed on Australia-ATLAS with error reading token data header: Connection closed lcg_cp: Communication error on send [2010813] (verified 20100814)
- https://gus.fzk.de/ws/ticket_info.php?ticket=61132
- production job issues
- See "Production" Activities section below
- analysis job issues
- See "Notes" section below
- AUSTRALIA-ATLAS_MCDISK became full [20100820]
- site storage token blacklisted in ddm and auto-cleaning applied to site
- http://savannah.cern.ch/support/?116330
- scheduled downtimes last week [20100819]
- disk server firmware upgrade https://next.gocdb.eu/portal/index.php?Page_Type=View_Object&object_id=20104&grid_id=0
- disk server firmware upgrade https://next.gocdb.eu/portal/index.php?Page_Type=View_Object&object_id=20104&grid_id=0
- upcoming scheduled downtimes
- electrical plant work for the datacentre - at risk - 20100903 https://next.gocdb.eu/portal/index.php?Page_Type=View_Object&object_id=20106&grid_id=0
- electrical plant work for the datacentre - at risk - 20100903 https://next.gocdb.eu/portal/index.php?Page_Type=View_Object&object_id=20106&grid_id=0
Outstanding Issues
- identified bug in SL53/54 x86_64 where a combination of specific LD_PRELOAD and LD_LIBRARY_PATH can cause core binaries (ls, rm etc.) to segfault
- causing issues with regards to release 15.5.1 testing. A modified setup for pilot users added to profile.d to get around this in the interim
- bugzilla report: https://bugzilla.redhat.com/show_bug.cgi?id=563759
McGill
Recent Issues
- the technical information and requirements in the issued RFP are available upon request; please contact Bryan who has a copy forwarded from Simon [20100720]
Production
Summary
CA Cloud Statistics Reference Link (Last Week) Overall Statistics Reference Link (Last Week)
- Within the CA Cloud:

- Within the None Cloud (see https://savannah.cern.ch/bugs/index.php?64507)


- Within the CA Cloud (Panglia View):


- How we fared to other ATLAS sites during the past week:

- Alternate Views (See link for last 3 days only):

- CA Cloud (last 3 days):

Failed Jobs
- From Panda Monitor (last week):


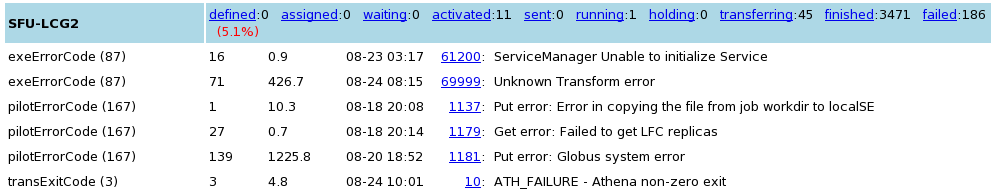

- From Dashboard (last week):
-
- TRIUMF-LCG2
name,rank,value
EXEPANDA_GET_FAILEDTOGETLFCREPLICAS,1,199
EXEPANDA_DQ2PUT_FILECOPYERROR,2,53
EXEPANDA_DQ2_STAGEIN,3,45
TRFERROR,4,39
TRF_SVRINIT ,5,32
EXEPANDA_JOBKILL_BYPILOT,6,9
EXEPANDA_JOBDISPATCHER_HEARTBEAT,7,5
TRF_UNKNOWN ,8,2
EXEPANDA_JOBDISPATCHER_NOREPLYTOSENTJOB,9,1
EXEPANDA_UNKNOWNERROR_JOBWRAPPERCRASH,10,1
TRF_SEGFAULT ,11,1
EXEPANDA_GET_SIZEMISMATCH,12,1
-
- CA-ALBERTA-WESTGRID-T2
name,rank,value
EXEPANDA_DQ2PUT_FILECOPYERROR,1,12
TRFERROR,2,5
EXEPANDA_JOBKILL_NOLOCALSPACE,3,2
EXEPANDA_GET_SIZEMISMATCH,4,1
TRF_UNKNOWN ,5,1
EXEPANDA_PILOTEXCEPTION,6,1
-
- Australia-ATLAS
name,rank,value
EXEPANDA_DQ2PUT_FILECOPYERROR,1,24
EXEPANDA_JOBKILL_NOLOCALSPACE,2,22
EXEPANDA_DQ2PUT_FILECOPYTIMEOUT,3,11
TRFERROR,4,7
EXEPANDA_GET_GLOBUSSYSTEMERROR,5,5
EXEPANDA_JOBDISPATCHER_HEARTBEAT,6,3
EXEPANDA_PILOTEXCEPTION,7,2
TRF_DBREL_TARFILE ,8,1
-
- SFU-LCG2
name,rank,value
EXEPANDA_PUT_GLOBUSSYSTEMERROR,1,132
EXEPANDA_GET_FAILEDTOGETLFCREPLICAS,2,27
TRF_SVRINIT ,3,16
TRF_UNKNOWN ,4,7
TRFERROR,5,2
EXEPANDA_DQ2PUT_FILECOPYERROR,6,1
You can find the meanings of the transform error codes on this link.
- My Notes:
- information missing in dashboard (production) still for CA-SCINET-T2.
- 3rd reminder sent to Dashboard Savannah (20100615) and dashboard-support@cern.ch
- previous reminder: sent to Dashboard Savannah (20100518)
- information missing in dashboard (production) still for CA-SCINET-T2.
- Yuri's notes: week (Aug 10 - Aug 16): Not Published This Week


Topic revision: r5 - 2010-08-24 - BryanCaron
Navigate ATLAS-Canada Wiki:
- * Home* * Activities * Analysis
- Computing
- Datasets
- Getting Started
- Grid Activities
- * Meetings* * People in ATLAS Canada * User Services
- Travel To CERN
Wikis:
 ATLAS
 Alberta
 McGill
 Montreal
 SFU
 Toronto
 TRIUMF
 UVic
ATLAS-Canada Institute Websites:
 UBC
 Carleton
 IPP
 York
 Create New Topic
 Search


 |
|

 Copyright © 2008-2026 by the contributing authors. All material on this collaboration platform is the property of the contributing authors.
Ideas, requests, problems regarding TWiki? Send feedback