TWiki> AtlasCanada Web>GridActivities>ATLASCanadaTier-2Operations>T2WeeklyReport20100112 (2010-01-12, AsokaDeSilva)
 EditAttach
AtlasCanada Web>GridActivities>ATLASCanadaTier-2Operations>T2WeeklyReport20100112 (2010-01-12, AsokaDeSilva) EditAttachTier1 and Tier-2 Weekly Report 2010-01-12
General News
* ADC News [20100112]- ADC Weekly Meeting - now scheduled for Wednesdays
- http://indicobeta.cern.ch/conferenceDisplay.py?confId=77820
 (20100106 meeting)
- analysis with pilots (within MB to be rediscussed in Feb-Mar)
- gLite + Argus alternative
- new acronym: MUPJ = multi-user pilot jobs
- http://indicobeta.cern.ch/conferenceDisplay.py?confId=77820
- 2009 Software and Computing Postmortem Workshop @ CERN : January 18-19, 2010
- ATLAS Tier-3 Workshop @ CERN : January 25-26, 2010
- ATLAS Tier-1/2/3 Jamboree @ CERN: February 9, 2010
- sites will be contacted in the next week if their published values of logicalCPU, physicalCPU, HEP-SPEC and kSI2K from their site BDIIs show abnormalities
- Release of UPDATE 07 to gLite 3. 2. Priority: Normal (20100107) (x86_64 link)
- New services released in SL5: CREAM, SCAS, GLEXEC for the WN, TORQUE server and TORQUE utils, Updated TORQUE client configuration, Updated lcg-info-dynamic-pbs
- Release of UPDATE 60 to gLite 3. 1. Priority: HIGH (20100111) (i386 link) and (x86_64 link)
- New version of lcg-vomscerts, New version of yaim for TORQUE, Update of TORQUE and MPI, Set of bug fixes for CREAM, Fix for the Torque info provider, New version of ICE for the WMS
- draft statistics available at http://lcg.web.cern.ch/LCG/accounting/Tier-2/2009/december-09/Tier2_Accounting_Report_December2009.pdf
- APEL installation at CA-ALBERTA-WESTGRID-T2 to be added to statistics database
- none in the past week
- shifters
- each site should have provided the names of at least one volunteer to perform shifts so as to share the load
- shifts are relatively light, during business hours, and involves checking a dashboard and making sure tickets are addressed in a timely way by the sites involved
- please contact Di, Reda and Mike regarding shifters volunteering from your site
- sites are reminded that they should have submitted to Di the electronically signed SLA between their site and ROC_Canada
- tested in SAM for ATLAS https://lcg-sam.cern.ch:8443/sam/sam.py?sensors=CE®ions=ROC_Canada&vo=atlas&order=SiteName&funct=ShowSensorTests, also within GangaRobot
- currently status as of this morning (WARN is ok)
- CA-ALBERTA-WESTGRID-T2 WARN (local squid server offline since 20091108)
- CA-SCINET-T2: Error (Frontier setup not yet defined as per standard ATLAS software installation procedures)
- SFU-LCG2 WARN (for both CEs; local is OK; Victoria squid is the backup but not online)
- TORONTO-LCG2 WARN (no local squid; primary backup points to ALBERTA squid but fails due to network routing issue + squid offline; secondary backup to SFU OK)
- TRIUMF-LCG2 WARN (ce1) OK (ce2) (local Frontier launchpad and BNL as backup)
- VICTORIA-LCG2 WARN (local squid access error; backup points to SFU squid)
- ATLAS_AUSTRALIA - WARN (local squid ok; backup access to VICTORIA error)
SAM Results
- Tier-1 Source URL: http://lcg-sam.cern.ch:8080/reports/site_avail.xsql
- Tier-2 Source URL: http://lcg-sam.cern.ch:8080/reports/t2/site_avail.xsql (old interface)
- new sites CA-ALBERTA-WESTGRID-T2 and CA-SCINET-T2 will not be added https://savannah.cern.ch/bugs/?60346
- new sites CA-ALBERTA-WESTGRID-T2 and CA-SCINET-T2 will not be added https://savannah.cern.ch/bugs/?60346
OPS VO
- Tier-2 Summary (All Sites)
- ops-t2-availability-summary-20100112.png:

- ops-t2-reliability-summary-20100112.png:

- CA-ALBERTA-WESTGRID-T2 ops-t2-alberta-20100112.pdf
- Australia-ATLAS ops-t2-australia-20100112.pdf
- CA-SCINET-T2 ops-t2-scinet-20100112.pdf
- SFU-LCG2 ops-t2-sfu-20100112.pdf
- VICTORIA-LCG2 ops-t2-victoria-20100112.pdf
APEL Accounting
APEL Publishing Status
- apel-status-ca-20100112.png:

- apel-status-aus-20100112.png:
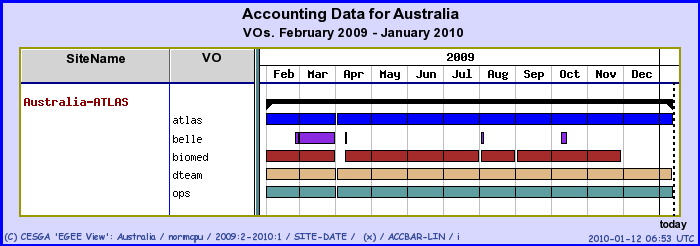
APEL Accounting Results
- apel-ca-20100112.png:

- apel-aus-20100112.png:

Site Reports
Alberta
Recent Issues
- summary of this weeks Savannah bugs and GGUS tickets for site:
- https://gus.fzk.de/ws/ticket_info.php?ticket=54601 CA-ALBERTA-WESTGRID-T2 lcg_cp communication error on send (20100112) [solved]
- https://gus.fzk.de/ws/ticket_info.php?ticket=54561 CA-ALBERTA-WESTGRID-T2 SAM job submission failures (20100108) [solved]
- https://gus.fzk.de/ws/ticket_info.php?ticket=53828 ALBERTA-LCG2 lcg-CE out-of-date (20091203) [in progress]
- http://savannah.cern.ch/bugs/?60346 to add CA-ALBERTA-WESTGRID-T2 to SAM results query and display pages (opened 20091208) [closed]
- https://gus.fzk.de/ws/ticket_info.php?ticket=54601
- production job issues
- See "Production" Activities section below
- analysis job issues
- See "Notes" section below
- ALBERTA-LCG2 site
- site offline to ATLAS since early December 2009 and currently in state of unscheduled downtime in GOCDB
- site storage migrated to CA-ALBERTA-WESTGRID-T2 site (except for 5.5 TB which are hosted on a server showing memory errors)
- site will be transitioned to Tier-3 functionality, upgrade to SL5 and return of SRM storage functions
- site offline to ATLAS since early December 2009 and currently in state of unscheduled downtime in GOCDB
- CA-ALBERTA-WESTGRID-T2 site installation status [20100111]
- network fibre cut between Calgary and Edmonton affecting WestGrid network access to cluster as well as end-to-end lightpath to TRIUMF at approx. 09:30 (20100111)
- brief period of 2 hours where internal network misconfiguration prevented proper communication between CE and local Torque-Moab server
- automatic failover of lightpath to research network WAN observed with return to lightpath just after midnight (see attached)
- UAlberta_lcgce01_last_108000-20100112.png:

- UAlberta_lcgce01_last_108000-20100112.png:
- network fibre cut between Calgary and Edmonton affecting WestGrid network access to cluster as well as end-to-end lightpath to TRIUMF at approx. 09:30 (20100111)
-
- update to Moab fairshare values for ATLAS activities based on NRAC allocations made [20100111]
- prior to this [20100108] various groups of jobs were not running due to the incorrect early-cluster commissioning fairshare settings for ATLAS being picked-up
- open items to be followed-up:
- APEL accounting information publishing
- SL5 WNs and additional CE
- need to update to dCache golden release cycle from currently running 1.9.3-3
- update to Moab fairshare values for ATLAS activities based on NRAC allocations made [20100111]
- following up on some ATLAS software installation problems following network hostname resolution changes for internal network prior to Christmas
- first noticed due to zero level of production activity in the previous reporting week with many jobs assigned but not running, waiting for input files [20100105]
Outstanding Issues
- squid server (vm) offline since restart to CA-ALBERTA-WESTGRID-T2 services following scheduled downtime for power maintenance [20091108]
- restart errors under investigation; automatic fail-over to secondary squid at SFU functioning as expected
SFU
Recent Issues
- summary of this weeks Savannah bugs and GGUS tickets for site:
- production job issues
- See "Production" Activities section below
- analysis job issues
- See "Notes" section below
Outstanding Issues
- identified one chassis of nodes where IB performance was degraded [20100105]
- nodes in chassis marked offline for repair by vendor
- SFU storage access protocol sanity check [20091022]
- missing dcap - Status of this?
- apel publishing [20090825]
- apel publishing information missing for October (see above plots) [20091013]
- publishing status for dteam appears empty since mid-July and coincides with appearance of the atcan group in the status graphs (see above)
- confirmed to coincide with change in VOMS group and role for direct tests by Sergey
- apel publishing results for September and October 2009 [20091110]
- low values published but not expected when comparing with ATLAS production dashboard for the same period
- GlueHostBenchmarkSF00 set to zero for both clusters in site BDII - fixed by site - reparsing and republishing to apel performed but still low values reported
- low-priority follow-up needed given that dteam jobs are observed regularly and consistently at other sites (Alberta for example)
Victoria
Recent Issues
- summary of this weeks Savannah bugs and GGUS tickets for site:
- https://gus.fzk.de/ws/ticket_info.php?ticket=54414 pnfs permissions errors (20100102) [verified]
- https://gus.fzk.de/ws/ticket_info.php?ticket=54419 pnfs permissions errors (20100103) [verified]
- https://gus.fzk.de/ws/ticket_info.php?ticket=54414
- production job issues
- See "Production" Activities section below
- analysis job issues
- see "Notes" section below
Outstanding Issues
- will likely switch to using the TRIUMF top-level BDII from the CERN-based BDII in order to help resolve observed timeouts [20100105]
- SCRATCHDISK became full [20091112]
- action to Bryan to write short srm script to generate warning notifications to sites when token areas approach becoming full
Toronto
Recent Issues
- summary of this weeks Savannah bugs and GGUS tickets for site:
- https://gus.fzk.de/ws/ticket_info.php?ticket=54131 CA-SCINET-T2 rgma error (20091215) [in progress]
- https://gus.fzk.de/ws/ticket_info.php?ticket=54441 CA-SCINET-T2 SAM job submission errors (20100105) [solved]
- https://gus.fzk.de/ws/ticket_info.php?ticket=53830 TORONTO-LCG2 update to lcg-CE (20091203) [on hold]
- https://gus.fzk.de/ws/ticket_info.php?ticket=53605 TORONTO-LCG2 lcg_cp timeout (20091124) [in progress]
- https://gus.fzk.de/ws/ticket_info.php?ticket=54131
- production job issues
- See "Production" Activities section below
- analysis job issues
- See "Notes" section below
- TORONTO-LCG2 site
- site offline to ATLAS; currently on unscheduled downtime in GOCDB
- CA-SCINET-T2 installation:
- new site certification completed by ROC_Canada: https://gus.fzk.de/ws/ticket_info.php?ticket=53710 [20091214]
- undergoing ATLAS configuration and validation (software release installation, gcc installation on WN, ...)
- new site certification completed by ROC_Canada: https://gus.fzk.de/ws/ticket_info.php?ticket=53710
Outstanding Issues
- Squid/Frontier access tests via ReadReal [20091028]
TRIUMF
Recent Issues
- summary of this weeks Savannah bugs and GGUS tickets for site:
- https://gus.fzk.de/ws/ticket_info.php?ticket=54565 FTS transfer errors with Australia on Australia side (network provider changes) (verified 20100109)
- https://gus.fzk.de/ws/ticket_info.php?ticket=54507 transfer errors due to SRM overload (solved 2010011)
- https://gus.fzk.de/ws/ticket_info.php?ticket=54291 SRM overload on 20091222 (solved 20100104)
- https://gus.fzk.de/ws/ticket_info.php?ticket=54565
- production job issues
- See "Production" Activities section below
- analysis job issues
- see "Notes" section below
Outstanding Issues
Australia-ATLAS
Recent Issues
- summary of this weeks Savannah bugs and GGUS tickets for site:
-
- https://gus.fzk.de/ws/ticket_info.php?ticket=54519 low transfer efficiency between proddisk and TRIUMF-MCDISK (20100107) [in progress]
- https://gus.fzk.de/ws/ticket_info.php?ticket=54532 upstream network problem (20100107) [merged with ticket 54519] [verified]
- https://gus.fzk.de/ws/ticket_info.php?ticket=54519
- production job issues
- See "Production" Activities section below
- analysis job issues
- See "Notes" section below
Outstanding Issues
McGill
Recent Issues
- status?
Outstanding Issues
Production
Summary
| site | success | failure | success (walltime) | failure (walltime) | efficiency | efficiency (walltime) |
|---|---|---|---|---|---|---|
| TRIUMF-LCG2 |
22124 | 986 | 608054765 | 33738235 | 95.7% | 94.7% |
| SFU-LCG2 |
8352 | 33 | 258119592 | 551487 | 99.6% | 99.8% |
| CA-ALBERTA-WESTGRID-T2 |
4351 | 1343 | 150658609 | 13562375 | 76.4% | 91.7% |
| VICTORIA-LCG2 |
1638 | 277 | 115746311 | 9404267 | 85.5% | 92.5% |
| Australia-ATLAS |
615 | 47 | 12452609 | 617641 | 92.9% | 95.3% |
| total | 37080 | 2686 | 1145031886 | 57874005 | 93.2% | 95.2% |
Failed Jobs
From Panda Monitor: FailedJobs.pdf From Dashboard: You can find the meanings of the transform error codes on this link.
TRIUMF: name,rank,value
EXEPANDA_DQ2PUT_FILECOPYERROR,1,887
EXEPANDA_JOBKILL_SIGTERM,2,56
EXEPANDA_JOBDISPATCHER_HEARTBEAT,3,33
EXEPANDA_DQ2GET_INFILE,4,7
EXEPANDA_DQ2_FILEADD,5,1
EXEPANDA_JOBKILL_BYPILOT,6,1
EXEPANDA_JOBKILL_BYSERVER,7,1
Alberta:
name,rank,value
EXEPANDA_DQ2GET_INFILE,1,673
EXEPANDA_JOBDISPATCHER_HEARTBEAT,2,637
EXEPANDA_DQ2_STAGEIN,3,32
EXEPANDA_DQ2PUT_FILECOPYERROR,4,1
Australia:
name,rank,value
EXEPANDA_DQ2_STAGEIN,1,36
EXEPANDA_DQ2PUT_FILECOPYERROR,2,5
EXEPANDA_JOBKILL_BYPILOT,3,3
EXEPANDA_GET_FAILEDTOGETLFCREPLICAS,4,1
TRFERROR,5,1
EXEPANDA_JOBDISPATCHER_HEARTBEAT,6,1
SFU:
name,rank,value
EXEPANDA_JOBDISPATCHER_HEARTBEAT,1,17
EXEPANDA_PUT_GLOBUSSYSTEMERROR,2,9
EXEPANDA_JOBKILL_SIGTERM,3,4
EXEPANDA_JOBKILL_BYPILOT,4,1
TRF_UNKNOWN ,5,1
EXEPANDA_DQ2_STAGEIN,6,1
Victoria:
name,rank,value
EXEPANDA_JOBDISPATCHER_HEARTBEAT,1,245
EXEPANDA_DQ2_STAGEIN,2,32
Notes
- How we fared to other ATLAS sites ...
| cloud | success | failure | success (walltime) | failure (walltime) | efficiency | efficiency (walltime) |
|---|---|---|---|---|---|---|
| BNL |
155181 | 3731 | 4690287716 | 157325800 | 97.7% | 96.8% |
| LYON |
77738 | 11782 | 3262308547 | 529624055 | 86.8% | 86% |
| NDGF |
81083 | 2155 | 1607194450 | 17755705 | 97.4% | 98.9% |
| PIC |
68689 | 478 | 1364688413 | 16373870 | 99.3% | 98.8% |
| RAL |
59971 | 1268 | 2749161030 | 62054822 | 97.9% | 97.8% |
| SARA |
47668 | 12751 | 1520634462 | 189100749 | 78.9% | 88.9% |
| FZK |
44390 | 279 | 1143988626 | 6220775 | 99.4% | 99.5% |
| None |
35819 | 5339 | 1083925958 | 27476227 | 87% | 97.5% |
| TRIUMF |
37080 | 2686 | 1145031886 | 57874005 | 93.2% | 95.2% |
| CNAF |
29102 | 2818 | 1112189026 | 28585474 | 91.2% | 97.5% |
| ASGC |
19454 | 1460 | 618638302 | 34386636 | 93% | 94.7% |
| CERN |
463 | 57 | 1598447 | 31194 | 89% | 98.1% |
| total | 656638 | 44804 | 2.0299646863e+10 | 1126809312 | 93.6% | 94.7% |
- My Notes:
- Australia offline since 2010-01-12 10:59:08 UTC.
- Alberta production queue offline GGUS ticket 54601 since 2010-01-10 20:20:18 UTC
- Low efficiencies ( < 95%):
- Alberta: GGUS ticket 54601
- Australia: stagein errors (network issues)
- Victoria: lost heartbeat (partly because of downtime and queue not drained.)
- ADCoS (Yuri's notes):
- - active tasks from PandaDB: 78
- -- by cloud: CA:10 CERN:1 DE:8 ES:8 FR:7 IT:6 ND:10 NL:7 TW:3 UK:6 US:12
- Wed Jan.6
- - CA/TRIUMF->UVIC FT f./fail to cont.on remote SRM.GGUS 54507 assigned
- Thu Jan.7
- - CA/TRIUMF ~40K/h datatape DDM&srmls requests causing timeouts.Experts informed.Elog 8481.
- - CA/TRIUMF<-AUSTRALIA 350 FT f.,eff.5%/GRIDFTP_ER./conn.reset by peer. GGUS 54519 in progress:several anomalies in networking.
- + CA/AUSTRALIA all jobs f./BDII no entry.GGUS 54532 solved:outage of the site BDII,unknown networking intervention,back now.
- Sat Jan.9
- + CA/TORONTO FT f./CONN./SRM.Site in DT.Blacklisted in DDM. Elog 8546,8548,8550.
- Sun Jan.10
- - CA/AUSTRALIA-ATLAS FT and job f./Globus_xio500 er.GGUS 54565,54519 in progress:network anomalies under investigation.Set offline.Elog 8857.
- Panda Stats:


Topic revision: r6 - 2010-01-12 - AsokaDeSilva
Navigate ATLAS-Canada Wiki:
- * Home* * Activities * Analysis
- Computing
- Datasets
- Getting Started
- Grid Activities
- * Meetings* * People in ATLAS Canada * User Services
- Travel To CERN
Wikis:
 ATLAS
 Alberta
 McGill
 Montreal
 SFU
 Toronto
 TRIUMF
 UVic
ATLAS-Canada Institute Websites:
 UBC
 Carleton
 IPP
 York
 Create New Topic
 Search


 |
|

 Copyright © 2008-2026 by the contributing authors. All material on this collaboration platform is the property of the contributing authors.
Ideas, requests, problems regarding TWiki? Send feedback