TWiki> AtlasCanada Web>GridActivities>ATLASCanadaTier-2Operations>T2WeeklyReport20090728 (2009-07-28, BryanCaron)
 EditAttach
AtlasCanada Web>GridActivities>ATLASCanadaTier-2Operations>T2WeeklyReport20090728 (2009-07-28, BryanCaron) EditAttachTier1 and Tier-2 Weekly Report 2009-07-28
General News
* APEL reports for WLCG updated for June to include missing statistics [re-published 2009-07-24]
       T2 CA East =  140% of MoU pledge (old was 105%)
              TORONTO-LCG2 --->  120549 kSI2K-Hrs
       T2 CA West = 90% of MoU pledge (old was 74%)
              ALBERTA-LCG2 --->  44244 kSI2K-Hrs
                  SFU-LCG2 --->  15593 kSI2K-Hrs
             VICTORIA-LCG2 --->   57041 kSI2K-Hrs
* request to sites for new accounts for pilot and poweruser0 roles within /atlas/ca group [distributed 2009-07-22] - tested at TRIUMF, ALBERTA, SFU (OK); debugging underway at TORONTO; VICTORIA pending
- See instructions for changes to site CE and SE to support the new roles
- transition all CA sites to new roles and pilots at the same time when confirmed ready; target is end of this week
- see dcache user-forum archives or forwarded email from Reda
- all production versions affected and require advertised patches
- we should take an inventory of our current site dCache configurations (hardware and service distribution) and deployed release versions
- Sites please look at your individual reports which have been updated to include "Site Tasks for Follow-up" [added 2009-07-14] and report on progress during meeting
- ATLAS CA STEP09 Site Reports: https://twiki.atlas-canada.ca/bin/view/AtlasCanada/Step09SiteReports
- STEP09 Summary Results http://gangarobot.cern.ch/st/step09summary.html

- Results Page: https://twiki.atlas-canada.ca/bin/view/AtlasCanada/SiteTestResults
- helpful to publish daily result summaries into a simple table template as done already for ALBERTA and TORONTO
SAM Results
- Tier-1 Source URL: http://lcg-sam.cern.ch:8080/reports/site_avail.xsql
- Tier-2 Source URL: http://lcg-sam.cern.ch:8080/reports/t2/site_avail.xsql
OPS VO
- ops-t2-availability-20090728.png:

- ops-t2-reliability-20090728.png:

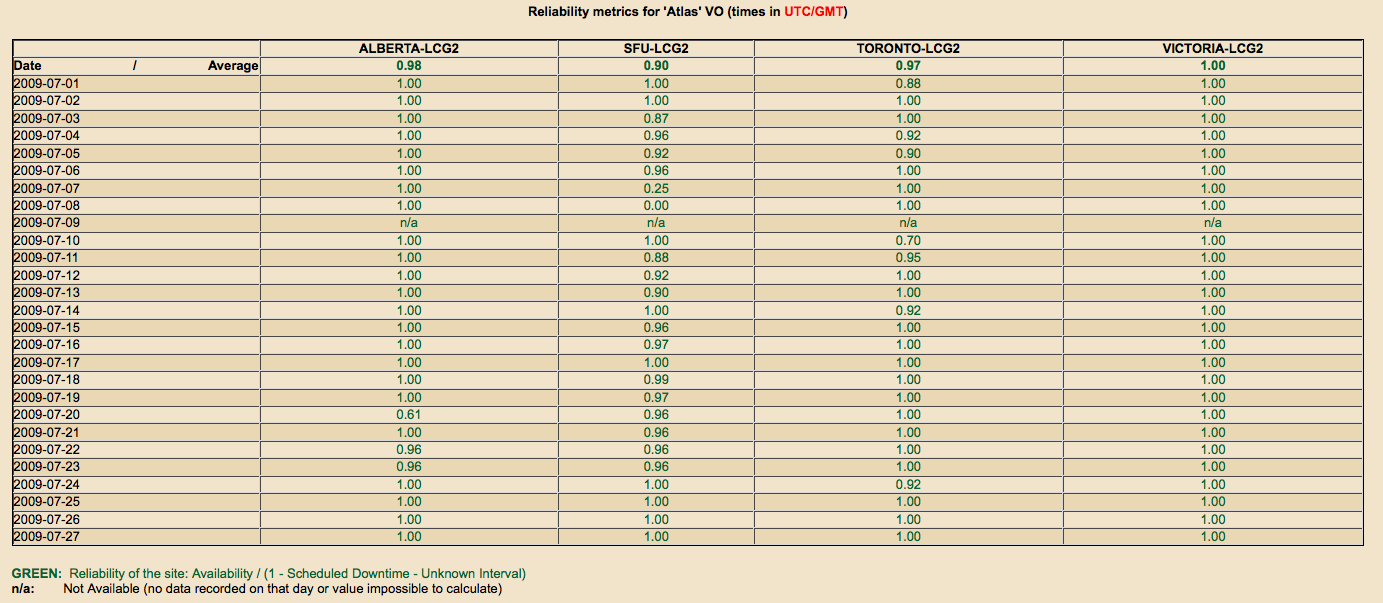
ATLAS VO
- atlas-t2-availability-20090728.png:

- atlas-t2-reliability-20090728.png:
APEL Accounting
APEL Publishing Status
- apel-gantt-20090728.png:

APEL Accounting Results
- apel-statistics-20090728.png:

Data Subscription Requests
- This past week: None
Site Reports
Alberta
Recent Issues
- software release 15.1.0 issues [2009-07-21]
- failing validation test which was previous successful in May and week ago
- correlation with powerbump of various WNs and atlas software release NFS server under investigation
- permissions problems in site SE pnfs for two dataset paths corrected [2009-07-22]
- advertised script from S.Liu to be applied for auto-correction of incorrect dir ownership [Done]
Outstanding Issues
* installation of grid services on new Westgrid-UA T2 site to be done * installation of grid services on new Westgrid-UA T2 site to be done * started preparations for new LCG-CE installation with dedicated set of a couple WNs for debugging purposes- few minor issues pending correction on existing T2 facility:
- full decoupling of WLCG accounts from cluster NIS to be done (see problem reported 2009-04-14)
- pnfsd.log to be added to log-rotate [2009-03-31]
- few WNs to be debugged with respect to missing stderr/stdout
- still need to add 2nd Gigabit Ethernet nic to dCache pools for internal network access from WNs to avoid NAT
SFU
Recent Issues
- implemented new roles and pilots; fully validated [2009-07-23]
- recurrent problems with missing files expected to exist on SE but unavailable during analysis and production jobs [2009-07-22]
- list of files expected to exist at SFU SE extracted from dump of TRIUMF LFC
- list of files expected to exist at SFU SE but not found in pnfs: lost_atlasmcdisk_pnfs.files
- Sergey creating list of files that exist in pnfs but are not on any pools
- Sergey additionally creating list of files that exist in pnfs but are not on any pools
- Reference ticket: https://savannah.cern.ch/bugs/?53395
- Reference ticket: https://savannah.cern.ch/bugs/?53395
- two reported job failures associated with reported too little disk space available on WN [2009-07-22]
- likely job ran in pool account home directory rather than in /scratch/atlas which has larger space available
Outstanding Issues
Victoria
Recent Issues
- site set offline in panda production [2009-07-25]
- release 14.2.25/14.2.25.1 installation issues to be checked; under revalidation
Outstanding Issues
Toronto
Recent Issues
- PRODDISK used by production jobs became full [2009-07-27] https://gus.fzk.de/ws/ticket_info.php?ticket=50543
- storage server went down with redundant power supplies failing on 2009-07-25 causing dCache to be down two days
- upon restoration PRODDISK increased in size slightly from 0.9 TB to approx. 1.7 TB
- implemented request for new roles and pilots at the site and currently are under validation tests [2009-07-27]
Outstanding Issues
- Still have two open GGUS tickets to resolve GIP information for the dCache 1.9
installation. Not movement on this in over a week.
https://gus.fzk.de/ws/ticket_info.php?ticket=48236
https://gus.fzk.de/ws/ticket_info.php?ticket=48235
McGill
Recent Issues
- status?
Outstanding Issues
- attempts to restore the McGill site to up-and-running state have resumed [2009-03-25]
- pilots (without payload) successfully running
- next target is successful SAM tests
- SE functionality still to be tested on current dCache instance with two pools
TRIUMF
Recent Issues
Outstanding Issues
Production
Summary
| site | success | failure | success (walltime) | failure (walltime) | efficiency | efficiency (walltime) |
|---|---|---|---|---|---|---|
| TRIUMF-LCG2 |
8605 | 610 | 113182575 | 6327851 | 93.4% | 94.7% |
| VICTORIA-LCG2 |
1709 | 1836 | 47333791 | 1301981 | 48.2% | 97.3% |
| SFU-LCG2 |
2406 | 46 | 35683906 | 443598 | 98.1% | 98.8% |
| TORONTO-LCG2 |
2240 | 79 | 104913306 | 6964346 | 96.6% | 93.8% |
| ALBERTA-LCG2 |
685 | 10 | 23277612 | 6912 | 98.6% | 100% |
| total | 15645 | 2581 | 324391190 | 15044688 | 85.8% | 95.6% |
Failed Jobs
(from Panda Monitor) FailedJobs.pdf (from dashboard) TRIUMF:name,rank,value
EXEPANDA_DQ2_STAGEIN,1,380
TRF_UNKNOWN ,2,97
EXEPANDA_JOBKILL_SIGTERM,3,65
EXEPANDA_JOBDISPATCHER_HEARTBEAT,4,35
TRF_ATHENACRASH ,5,20
EXEPANDA_DQ2PUT_FILECOPYERROR,6,11
EXEPANDA_JOBKILL_BYPILOT,7,2
Alberta:
name,rank,value
TRF_UNKNOWN ,1,10
SFU:
name,rank,value
TRF_UNKNOWN ,1,26
EXEPANDA_DQ2_STAGEIN,2,8
EXEPANDA_JOBDISPATCHER_HEARTBEAT,3,5
TRF_OUTFILE ,4,2
EXEPANDA_GET_ADLER32MISMATCH,5,2
TRF_INFILE_NOTFOUND ,6,1
TRF_SEGFAULT ,7,1
EXEPANDA_JOBKILL_BYPILOT,8,1
Toronto:
name,rank,value
EXEPANDA_DQ2PUT_FILECOPYERROR,1,70
TRF_SEGFAULT ,2,5
TRF_OUTFILE ,3,2
TRF_INFILE_NOTFOUND ,4,1
EXEPANDA_JOBKILL_BYPILOT,5,1
Victoria:
name,rank,value
TRF_ARG ,1,1811
EXEPANDA_DQ2GET_INFILE,2,8
EXEPANDA_DQ2PUT_FILECOPYTIMEOUT,3,7
EXEPANDA_JOBKILL_BYPILOT,4,4
TRF_UNKNOWN ,5,2
TRF_SEGFAULT ,6,2
TRF_OUTFILE ,7,1
EXEPANDA_DQ2PUT_FILECOPYERROR,8,1
Notes
Daily mailings sent about production failures for each site. Please see those for details. These are the reasons for the failures at sites with efficiencies < 95%:- TRIUMF:
- For staging input file issue (10G network card issue to pool node): GGUS tiicket #50469 https://gus.fzk.de/ws/ticket_info.php?ticket=50469
- For staging input file issue (10G network card issue to pool node): GGUS tiicket #50469 https://gus.fzk.de/ws/ticket_info.php?ticket=50469
- Victoria:
- Suspected corrupted release (142.25.*) issue. https://savannah.cern.ch/bugs/?53611
- Suspected corrupted release (142.25.*) issue. https://savannah.cern.ch/bugs/?53611


| I | Attachment | History | Action | Size | Date | Who | Comment |
|---|---|---|---|---|---|---|---|
 pdf |
DashboardSummary.pdf | r1 | manage | 97.1 K | 2009-07-28 - 18:11 | AsokaDeSilva | |
| pdf |
FailedJobs.pdf | r1 | manage | 42.3 K | 2009-07-28 - 18:11 | AsokaDeSilva | |
 png |
apel-gantt-20090728.png | r1 | manage | 22.6 K | 2009-07-28 - 15:52 | BryanCaron | |
| png |
apel-statistics-20090728.png | r1 | manage | 127.9 K | 2009-07-28 - 15:52 | BryanCaron | |
| png |
atlas-t2-availability-20090728.png | r1 | manage | 220.7 K | 2009-07-28 - 15:44 | BryanCaron | |
| png |
atlas-t2-reliability-20090728.png | r1 | manage | 144.1 K | 2009-07-28 - 15:45 | BryanCaron | |
 files |
lost_atlasmcdisk_pnfs.files | r1 | manage | 148.0 K | 2009-07-28 - 18:18 | BryanCaron | |
| png |
ops-t2-availability-20090728.png | r1 | manage | 222.2 K | 2009-07-28 - 15:43 | BryanCaron | |
| png |
ops-t2-reliability-20090728.png | r1 | manage | 145.2 K | 2009-07-28 - 15:43 | BryanCaron |
Topic revision: r10 - 2009-07-28 - BryanCaron
Navigate ATLAS-Canada Wiki:
- * Home* * Activities * Analysis
- Computing
- Datasets
- Getting Started
- Grid Activities
- * Meetings* * People in ATLAS Canada * User Services
- Travel To CERN
Wikis:
 ATLAS
 Alberta
 McGill
 Montreal
 SFU
 Toronto
 TRIUMF
 UVic
ATLAS-Canada Institute Websites:
 UBC
 Carleton
 IPP
 York
 Create New Topic
 Search


 |
|

 Copyright © 2008-2026 by the contributing authors. All material on this collaboration platform is the property of the contributing authors.
Ideas, requests, problems regarding TWiki? Send feedback